
Weekly roundup
AI model drops: SwitchX 3.0 and Seedream 5.5
A good week if you shoot real plates and finish with AI. Beeble and ByteDance both put out video tools worth an afternoon, ByteDance Seed sorted out the colour drift that creeps into repeated image edits, and ElevenLabs gave editors a better transcriber. The language models, plus a few voice and image releases we didn't have room for, are listed at the bottom.
SwitchX 3.0: a new world behind your handheld plate
Beeble's video-to-video model now runs on MiniMax H3, retrained on Beeble's own data, and it's built for one job: replacing the world around a live-action shot. You can give it up to four references, say a wide of the set, a prop and a storyboard frame, and it pulls them into one shot. Backgrounds move far more than in 2.0, so traffic, crowds, fire and snow, and Beeble says the new world stays locked to the camera even when you're handheld, orbiting or running with your subject. It's in the Beeble app and Canvas now, with output up to 4K.
Seedance 2.5 flash: the same tricks, twice as quick
Volcano Engine's faster tier of Seedance 2.5 keeps most of what the flagship does: single clips up to 30 seconds, and up to 10 images, 5 videos and 5 audio clips as references in one go. The catch is resolution, 480p or 720p only. ByteDance says it generates twice as fast and costs less, so it's the one for blocking out ideas and batch runs before you spend on the full model. The listing is on the Chinese Ark console for now; our Model drops line has the link.
Seedream 5.5: edit the same frame 100 times without drift
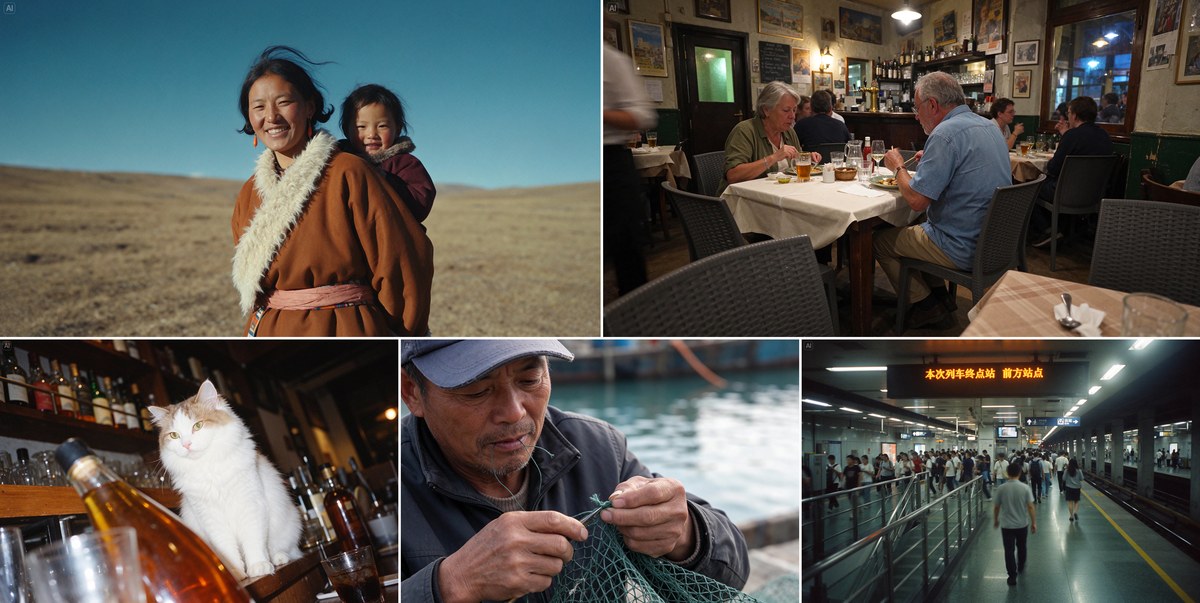
ByteDance Seed trained this image model to leave untouched areas alone at the pixel level, so colour doesn't shift and detail doesn't fall apart as you keep editing one image. Their demo runs 100 edits in a row on the same person. It also makes native RGBA images with full and partial transparency, which means cut-out elements for comps and titles with no background removal or edge clean-up. Skin, lighting and small text look more natural too, and Seed says usability in its film and TV tests was more than double Seedream 5.0 Pro's.
Scribe v3: transcripts that get the speakers right
Not a generator, but anyone logging interviews will feel it. ElevenLabs says its new speech-to-text model makes 27% fewer word errors than Scribe v2 across 102 languages, and 17% fewer speaker-label mistakes on recordings with three or more people. You can feed it up to 1,000 key terms, handy for character names and odd place names, and choose whether numbers come back as digits or words. It's now the default in the ElevenLabs app, which sits on our ElevenLabs page.
Also dropped
- Gemini 4 Hydrogen Google, 12 Nov 2026
Google's fast everyday Gemini 4 model for coding and agent work, out now on every Google AI Studio and Gemini API tier, in the Gemini app and in Search. - Qwen4-Max-Preview Alibaba, 11 Nov 2026
Preview of the next flagship Qwen model, reading text, images and video with deep reasoning, tool calling and web search. Token Plan only, from 11 to 25 Nov, then retired. - MiniMax H3-Image MiniMax, 10 Nov 2026
Open-weight image model from the H3 family: text-to-image and editing in one checkpoint, up to 16 reference images, 4K (4096 x 4096) in under 10 seconds. - ZONOS3-Mini Zyphra, 9 Nov 2026
Compact open-weight text-to-speech model with zero-shot voice cloning in 43 languages; 100M active parameters, real time on laptops, phones and in the browser. - Muse Ember Meta, 9 Nov 2026
Meta's smallest, cheapest Muse model for high-volume agent work; reads text, images, audio and video, 1M-token context, US$0.10/US$0.50 per million tokens on the Meta Model API. - Claude Fable 5.2 and Mythos 5.2 Anthropic, 9 Nov 2026
Anthropic's generally available Fable upgrade: stronger coding, reasoning and vision than Fable 5.1, up to 30% faster generation, $8/$40 per million tokens with optional fast mode, on Claude apps, API (claude-fable-5-2), AWS, Google Cloud and Azure. Mythos 5.2 is the same underlying model without the cyber and biology safeguards, for Cyber and Life Sciences Verification Program organisations. - Gemini Omni 1.2 Flash Google, 5 Nov 2026
Generally available on the Gemini API and Google Cloud: native 15-second video (up from 10), multi-turn conversational editing, stronger reference following, and a 30% price cut to $0.07 per second for 720p. Also in Google Vids, with up to three 15-second videos a month at no cost for anyone with a Google account or Workspace.
Related on AI Field Notes
- ElevenLabs: our model notes Model notes
- Film news, November 2026 News month
Every claim here comes from the maker's own page, linked above. Licence tags are what the maker's licence or terms said on the day we filed, not legal advice, so check the linked terms before client work. The full day-by-day list is on Model drops, and older roundups are in the weekly archive.